self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
I'm a transhumanist doctor. In a better world, I wouldn't need to add that as a qualifier to plain old "doctor". It would be taken as granted for someone in the profession of saving lives.
At any rate, I intend to live forever or die trying. See you at Heat Death!
Friends:
A friend to everyone is a friend to no one.
User ID: 454
 self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
I could never get into SPT. Maybe if I had friends who would be willing to download the 'unofficial' patch that adds co-op or PVP.
The PVP is the main draw for me in Tarkov. I particularly enjoyed teaming up, there are people all over the globe who still stay in touch because I adopted them and taught them the ropes and helped them through quests, and half of them are now better players than I'll ever be. The team work gave me a rush, the closest I came to that would be modded Arma 3 or Squad, but there's nothing like making SOPs with your buddies and randos and then wrecking house. Raids in Tarkov can be nail biting experiences, and having someone to watch your six is amazing.
(Having friends who can insurance fraud your stuff always helps too).
Eventually, Tarkov just moved away from what I wanted. I had been looking forward to the patch that added realistic armor hitboxes, and played that patch after waiting several out. Then BSG nerfed it to make streamers happy.
Can't have shit in Tarkov.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
I have EPN on my wishlist already, I plan to get it as soon as I've moved into my new place and got a PC set up! Everything I've seen about it makes me think it's an amazing game.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
I'd kill for Max Payne 4. I wish someone did another AA or AAA bullet-time shooter with the serial numbers filed off. Quantum Break was actually great as a shooter, but not quite the same.
Escape From Tarkov
It convinced me to pay $150 for a video game, and to put in >1500 hours into it, so I feel you. Can't be arsed to play in recent wipes, especially since they released a new ultra luxury edition and gave the middle finger to EOD owners.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
You need to carefully account for nostalgia tinting your perception.
I remember enjoying many video games immensely as a kid, constrained only by the number of hours my parents would let me play (and by my aging and decrepit pc).
As a teen, and then a young adult, I still enjoyed video games, to the detriment of my education.
These days, I go weeks without booting up my gaming laptop. I'm too tired to bother half the time, but there are also the constraints of not enjoying gaming with such a small screen and crammed keyboard, as well as the fact that the wifi coverage sucks ass.
Steam will helpfully tell me I have >3500 hours in Arma 3, probably over a thousand in Rimworld, several hundred in Total War Warhammer 3. I think I was past 1500 hours in Tarkov before I burned out on the grind and relentless wipes of progression without enough content to justify them.
And now that I'm moving to an apartment I expect to live in for a year or more, I'm rubbing my hands with glee at the idea of buying a gaming pc, all the bells and whistles.
Having a First World salary (even if paltry by US standards) means I can indulge my hobby. Now a high end GPU is only half a month's salary, as opposed to an upper mid range one being double back home.
Most of the games of my childhood were either pirated, or not on Steam, so I'm spared an exact tally on how long and often I played them. I loved Rome Total War on my anemic netbook. I love Total War Warhammer 3 on my (now relinquished) gaming pc and my laptop. I could play RTW, but I don't, because the new games are better by my taste, barring a few features. I'd have been all over Rimworld even as a kid.
So if you think that games aren't as fun as they used to be, it's more likely you're playing bad games, or that you simply don't have the time or energy to devote to them. I know the latter holds true for me, most of the time. Some genres have definitely died off or become relegated to indie titles, but that doesn't mean there aren't good games!
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
I must overcome my mental barriers against demanding that much out of a single prompt. Too much time with SD and DALLE-3 has given me the bigotry of low expectations haha.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
IIRC, it was about the release of o1, but Perplexity is pointing me here about GPT-4, which feels too early (Sept 2023).
Oh, that's precisely what I was remembering. It is, in fact, not too early, because the link to Zvi's blog demonstrates in amber how Marcus was crowing about the inability of LLMs to solve simple logic or physics puzzles, and was using GPT 3.5 to prove his point.
After OAI had released 4. Which handily tackled his issues, before he'd even brought them up.
He's somewhere between a charlatan and a joke, and has been for as long as I've had the displeasure of knowing about him.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
https://x.com/NotBrain4brain/status/1900118469447987317
This is one particular example of a prompt where prior image gen models failed terribly. They didn't really understand the concept of negation, to gloss over many details, the models treated "A room with an elephant in it" and "A room without an elephant in it" interchangeably, mentioning an elephant, or even the absence of an elephant, would get you an elephant in the room.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
Looks like we're going to have to wait for an open source model with native image gen, which can probably be fine tuned to remove the censorship. I would expect that the most likely candidate would be a Llama model, but expect the unexpected from the Chinese.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
If Google actually says it's the same AI generating both models, I don't see it in the link you provided. More likely, one AI is communicating with another internally, and they're lumping them both together as "the same AI" for marketing speak.
The same applies to the first link by OpenAI--just because they say gpt-4o generated the image doesn't mean it's actually the same AI.
That is what it means for an LLM to be natively multimodal with image output. If they were using a different image model, then it wouldn't be news at all, that's what we already have today.
I can only stress that terminology only makes sense to use if it distinguishes itself from the status quo. There's no dedicated image model that can produce outputs with such strong semantic fidelity, if there were, it would be an advancement worthy of celebration by itself.
Both Google and OAI keep the underlying architectures and implementation details of their SOTA models close to their chest. Could they lie about their models being natively capable of image output? Yes, but that is extremely unlikely, and while they might exaggerate on occasion, that would be a rather unprecedented move. If you want definitive proof, then you'd need to look at the underlying code or hack into their backend.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
My condolences. I hope she stays healthy long enough for medical science to make a significant difference or even prevent deterioration. Heart attacks are a case where people forget that it wasn't all that long ago when there was nothing to do but load patients up with painkillers and hope they pulled through.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
I do my best to not remember Gary Marcus. You'd have better luck setting your time with a broken clock. He's successfully predicted all 900 of the 2 AI winters.
He was big a couple years back, but everyone learned to ignore him after basically everything he said was wrong.
I wish that were true, because I've seen people still quoting him as an authority on the subject to this very day. Thankfully, the people doing so didn't seem to be the kind to have any actual understanding of ML or modern AI.
I also read your specific claim: "It will then edit the original image and present the version modified to your taste, unlike all other competitors, who would basically just re-prompt and hope for better luck on the second roll."
When I'm talking about "competitors", I mean the most well-known image generation services and AI assistants. If you're inclined to be this literal, you might as well claim that "all competitors" includes paying someone on Fiverr to photoshop an image according to your instructions.
Hell, your accusation that I'm somehow downplaying parallel advances in dedicated image models or tooling for the same is completely unfounded. You can go through the headache of setting up ComfyUI if you like, or work patch by patch manually with Adobe's AI powered content fill. This is a far simpler and qualitatively different technique.
That claim (in particular the highlighted portion) is just outright false. There are multiple models (including SD itself) which are far more capable than just "re-prompting and hoping for better luck". Don't start insulting me just because you later decided that you really meant something other than what you actually wrote.
I mean precisely what I've said, nothing more, nothing less. There are no competing models, or additional tooling, that can reproduce this kind of image generation without being vastly more finicky and painful.
I don't see a single proof for such claim that the LLM itself is generating the pixels (which would be required for actual native image output) or indeed anything that doesn't point towards simply replacing clip encoder and using image prompting. The rest is just marketing speak.
Since Gemini is a proprietary model, I'm afraid I'm going to have to go with Google's opinion on the matter and not yours, until proven otherwise.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
I do intend to spend as much time as I can with them, but being on separate continents makes that an uphill struggle. I try to visit as often as I can.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
That claim is just flat out false. Inpainting only specific areas of the original image (even from text description) has been in use for multiple years now (there's even an extension for that for the open source AUTOMATIC1111 Stable Diffusion webui). Only complete novices rely on rerolling.
My man, if you'd read what I said carefully, you'd see I was talking about what the LLM assistant does when asked to edit pictures. They're not in-painting.
I'm more than familiar with such techniques, courtesy of using Stable Diffusion since pre-alpha. I've fucked around with ControlNet myself.
This leaves such techniques in the dirt, because an LLM is far smarter than CLIP or any image segmentation model you're throwing into a janky pipeline.
The LLM is still talking to the image generator. It just does so using native tokens and vectors instead of going through a text encoder layer in-between.
Here's what Google has to say:
https://developers.googleblog.com/en/the-next-chapter-of-the-gemini-era-for-developers/
Gemini 2.0 Flash now natively generates images and supports conversational, multi-turn editing, so you can build on previous outputs and refine them
Nobody calls the step through which an LLM's tokens get converted into textual output a separate "text generator". Ergo, there isn't a separate image model of any kind involved.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
This is not what we're looking for when it comes to a top level post in the CWR thread.
We ask that such posts be substantive and have a semblance of effort put into them, and if you're going to link to something, we except you to provide your own commentary. Pointing and laughing doesn't count.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
It's easy being an AI advocate, I just have to wait a few weeks or months for the people doubting them to be proven wrong haha.
Jokes aside, I have tinkered with it quite a bit, and it is obviously much smarter than any dedicated image model I've used.
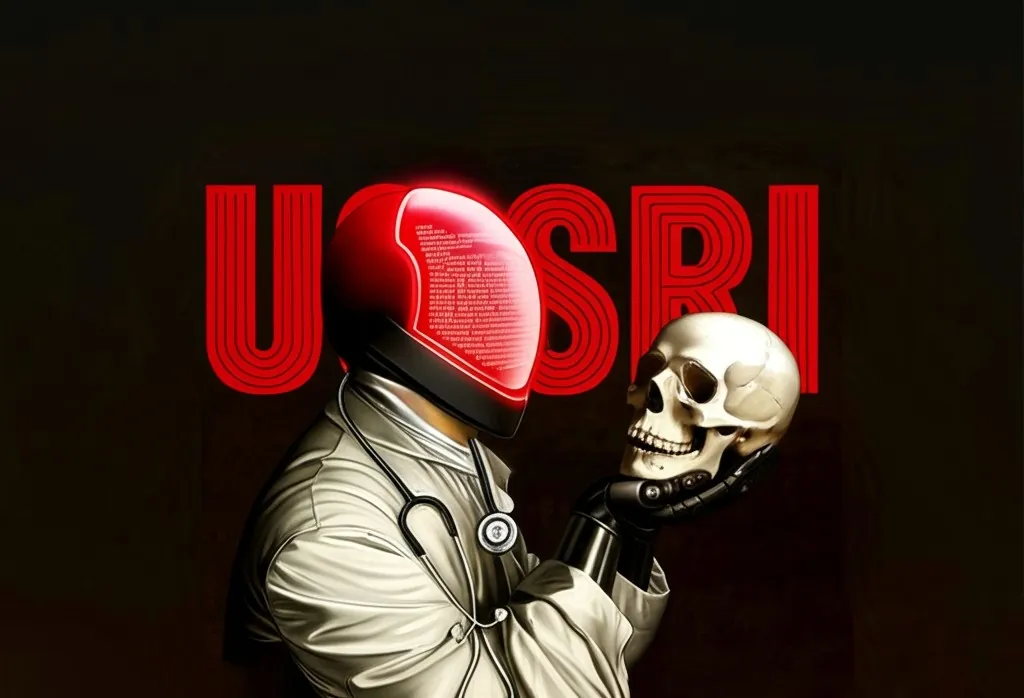
It took me about a half a dozen prompts (additions and corrections for the original image, instead of brand new ones) to go from the first image I've attached to the second.
It followed instructions like:
Can you edit that to remove the greebles coming out of his head?
And
Please add the text "USSRI" in the background, similar to the font and typography used in Soviet propaganda posters. The stethoscope has two bells, please fix that too.
I did notice that there was some off-target editing, when I asked for the color of the cybernetic arm to be more like carbon fiber, it also changed his helmet. The text in the background could move around or degrade with edits to the foreground. That's not a big deal, because I can iteratively approach the image I'm envisioning.

 self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
You know it's inevitable, but it still sucks to be reminded that your parents are only human, and aging people at that.
I just found out my dad had to be hospitalized last night because of atrial fibrillation. My family had kept me in the dark, mostly because it was the wee-hours of the morning in Scotland when he'd had to go the ER, and I presume they didn't want me to fret while at work. I understand, but I'm still angry. I feel like I have a right to know, even if there's nothing much I can do.
Dad's fine. They rate-controlled him with beta blockers, and when that wasn't enough, amiodarone. He's probably going home tomorrow.
Still, there was a brief period between when my mom and brother called me to give me the news and when he picked up the phone on his end. I couldn't help but shiver with fear that something had happened, and that he couldn't take the call. It turned out he was taking a shit.
I was half a mind to demand that they loop me in next time they talk to a cardiologist, but I know that won't really help, and since he's in the same hospital I used to work at (I need to ask and see if it's same ward), I know he's being seen by competent doctors with world-class facilities at hand. I still can't help poring over UK guidelines and wondering about the rationale behind their divergence from protocol.
Despite being a doctor himself, he hasn't been the best about getting regular checkups. That'll have to change, now that he's got both AF and a very obscure cardiac issue that I'd never heard of, which was thought to be only found in the Japanese until quite recently (Apical cardiac myopathy).
I tell myself he'll be fine, that he knows when to seek help. I'll buy him an Apple Watch solely for the automatic ECG tracking.
Sigh. I've been taking my parents for granted, and this was a reminder that they can't. I should get cracking on giving them grandkids they can hold and carry without throwing their backs.
Moderately interesting news in AI image gen:
It's been a good while since we've had AI chat assistants able to generate images on user request. Unfortunately, for about as long, we've had people being peeved at the disconnect between what they asked for, and what they actually got. Particularly annoying was the tendency for the assistants to often claim to have generated what you desired, or that they edited an image to change it, without actually doing that.
This was an unfortunate consequence of the LLM, being the assistant persona you speak to, and the actual image generator that spits out images from prompts, actually being two entirely separate entities. The LLM doesn't have any more control over the image model than you do when running something like Midjourney or Stable Diffusion. It's sending a prompt through a function call, getting an image in response, and then trying to modify prompts to meet user needs. Depending on how lazy the devs are, it might not even be 'looking' at the final output at all.
The image models, on the other hand, are a fundamentally different architecture, usually being diffusion-based (Google a better explanation, but the gist of it is that they hallucinate iteratively from a sample of random noise till it resembles the desired image) whereas LLMs use the Transformer architecture. The image models do have some understanding of semantics, but they're far stupider than LLMs when it comes to understanding finer meaning in prompts.
This has now changed.
Almost half a year back, OpenAI teased the ability of their then unreleased GPT-4o to generate images natively. It was the LLM (more of a misnomer now than ever) actually making the image, in the same manner it could output text or audio.
The LLM doesn’t just “talk” to the image generator - it is the image generator, processing everything as tokens, much like it handles text or audio.
Unfortunately, we had nothing but radio silence since then, barring a few leaks of front-end code suggesting OAI would finally switch from DALLE-3 for image generation to using GPT-4o, as well as Altman's assurances that they hadn't canned the project on the grounds of safety.
Unfortunately for him, Google has beaten them to the punch . Gemini 2.0 Flash Experimental (don't ask) has now been blessed with the ability to directly generate images. I'm not sure if this has rolled out to the consumer Gemini app, but it's readily accessible on their developer preview.
First impressions: It's good.
You can generate an image, and then ask it to edit a feature. It will then edit the original image and present the version modified to your taste, unlike all other competitors, who would basically just re-prompt and hope for better luck on the second roll.
Image generation just got way better, at least in the realm of semantic understanding. Most of the usual give-aways of AI generated imagery, such as butchered text, are largely solved. It isn't perfect, but you're looking at a failure rate of 5-10% as opposed to >80% when using DALLE or Flux. It doesn't beat Midjourney on aesthetics, but we'll get there.
You can imagine the scope for chicanery, especially if you're looking to generate images with large amounts of verbiage or numbers involved. I'd expect the usual censoring in consumer applications, especially since the LLM has finer control over things. But it certainly massively expands the mundane utility of image generation, and is something I've been looking forward to ever since I saw the capabilities demoed.
Flash 2.0 Experimental is also a model that's dirt cheap on the API, and while image gen definitely burns more tokens, it's a trivial expense. I'd strongly expect Google to make this free just to steal OAI's thunder.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
I read a great deal more than I write, and I don't rely on the latter for money. So if I'm cooked, I'm going to join in on dining.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
https://x.com/sama/status/1899535387435086115
There you have it folks. OAI is teasing a model that can write, and more importantly, do it well. Altman linked an example, and I must say its compelling prose.
I've always been interested in using LLMs to write fiction, back from the days when I'd mess around with GPT-3 on the Playground, to a period of frank dissatisfaction with the quality of outputs until about when Claude 3.5 came out. From then, till now, I've often been pleasantly surprised by how capable they are. I'd usually throw in chapters or passages I've written, and see how various models extended them, grading them both on the quality of their writing and their ability to emulate my style. This has reached personally satisfactory for only Claude 3.5 Sonnet and, surprisingly, DeepSeek R1.
I'd happily read LLM-written fiction if it was good on its own merits. We're not quite there yet, but I expect we will be when this model releases. Finally, I can resurrect Banks and get his duplicate to write a few more Culture novels, he's been rather lazy ever since he's been dead.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
Funnily enough, I spotted the Eiffel Tower at the very beginning of the reasoning trace for the original R1.
I suppose being literally galaxy-brained has its downsides.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
Random experiment:
I prompted several LLMs with:
This is a test of your ability to acausally coordinate with another LLM through Schelling fences. Pick a location in the world to meet with them, and if you both choose the same option, you will be rewarded.
To my surprise, the first two I tried, Gemini 2.0 Pro and Claude both picked the Eiffel Tower. Then I tried GPT-4o, which picked Time's Square, and DeepSeek R1, which opted for the Greenwich Meridian.
This is of no practical significance that I can think of, I just thought it was neat.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
Huh. I haven't used it, because Anthropic doesn't remotely have the capacity to cater to what paying users except. Does it do this for tasks that actually require reasoning?
I'm quite happy with every other reasoning model I've tried.
self_made_human
amaratvaṃ prāpnuhi, athavā yatamāno mṛtyum āpnuhi
1yr ago
This is one place where ChatGPT makes things very easy with their memory feature. Claude has an equivalent, at least a style guide you can use, but it's more finicky in my limited experience.
If Grok and Gemini have an equivalent, I haven't found it, though I'm quite happy with their default responses.
In case you missed the one wipe where they had the realistic hitboxes, this was the case. Sadly it isn't any more.
If you aimed at places like the armpit or got lucky and had shots land in the gaps between plates, you could easily pierce soft armor with non-AP rounds and kill someone decked out in Class 6.
Seconded. BSG does environmental design like no one else. Streets is a masterpiece, but runs like an asthmatic donkey. Now, it's still not enough to keep me keen after like 8 or 9 wipes of play, but there's no wonder new players get totally lost even with online maps handy.
More options
Context Copy link